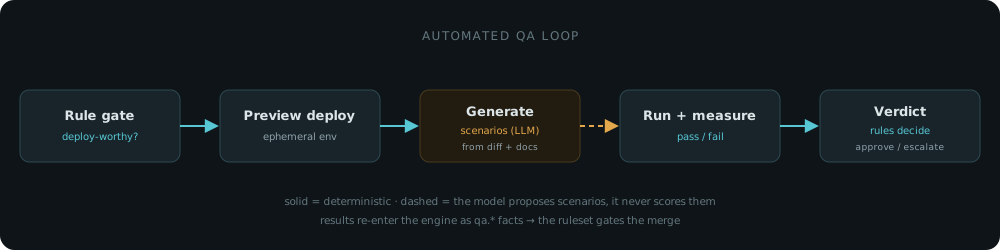
Static review tells you whether a diff looks right. It can't tell you whether the change actually works. Automated QA closes that gap without handing the decision to a model: the rules decide when a PR earns a throwaway deployment, an LLM generates the test scenarios, the scenarios run, and the results come back as facts the engine gates on.
The model proposes scenarios. It never decides the outcome — pass/fail is measured, and the verdict stays with the rules.
The idea
Once a PR is deemed deploy-worthy by policy — green CI, off a critical path, small enough to be safe — Talooner can:
- Spin up an ephemeral preview deployment of the PR's code.
- Ask a model to generate test scenarios from the diff, the PR description, and the module's own docs — the behaviours a reviewer would want exercised.
- Run those scenarios against the preview environment.
- Fold the results back into the engine as facts —
qa.scenarios_total,qa.scenarios_passed,qa.failed_scenarios,qa.coverage_confidence. - Let the rules decide what the outcome means: approve, comment the failures, request changes, escalate to a human, or tear the environment down.
What it looks like in a ruleset
// Only PRs that already pass the cheap gates earn a deployment.
define "deploy_candidate" {
  attr "pr.tests_passing" == true
  attr "pr.lint_passing"  == true
  attr "pr.draft"         == false
  not is "critical_path"
}

// Rules ask for the deployment and the generated scenarios — they aren't automatic.
rule "Run automated QA on deploy candidates" {
  for records where type == "pr" and is "deploy_candidate"
  do deploy_preview "pr"
  do qa_scenarios "pr"
}

// The engine gates on the measured result, not on the model's opinion.
rule "Block on failed QA scenarios" {
  for records where type == "pr"
    and attr "qa.scenarios_passed" < attr "qa.scenarios_total"
  block "merge"
  do block "pr.merge"
  do comment "pr" "Automated QA failed {attr.qa.failed_scenarios} — see the run before merging"
  reason "generated scenarios failed"
  priority HIGH
}

// Low coverage confidence is a human's call, not an auto-approve.
rule "Escalate thin QA coverage" {
  for records where type == "pr"
    and attr "qa.coverage_confidence" < 0.8
  do comment "pr" "QA coverage looks thin (confidence {attr.qa.coverage_confidence}) — a human should confirm the risky paths are exercised"
}
Why route it through rules instead of a model
- The decision to deploy is policy, not a guess. A rule — not a model — decides which PRs are safe to stand up. Fork PRs, critical paths, and secret-touching changes simply never enter the loop.
- Scenarios are generated; outcomes are measured. The LLM's job ends at proposing what to test. Whether those tests pass is a fact, and facts are what the engine gates on. A confident, wrong model can't approve a broken PR.
- Every run is auditable. The generated scenarios, the environment, and the
pass/fail results are all recorded as facts — you can
explainexactly why a PR was blocked or approved. - Confidence is explicit.
qa.coverage_confidencelets a rule distinguish "verified working" from "we couldn't meaningfully exercise this" and route the second case to a human.
Generated scenarios are real tests
The scenarios aren't a prose summary of "what to check" — they're executable tests the runner can actually run against the preview. A functional scenario, generated from the diff, the PR description, and the module's docs, comes out as a Jest test:
// talooner-generated · scenario: "a user can rename themselves, but nobody else"
// derived from: diff app/controllers/users_controller.rb, PR body, docs/users.md
import { test, expect } from '@jest/globals';

const DEPLOY = process.env.PREVIEW_URL;
const asAlice = { 'content-type': 'application/json', authorization: `Bearer ${process.env.ALICE_TOKEN}` };

test('updating your own name is saved', async () => {
  const res = await fetch(`${DEPLOY}/api/users/alice`, {
    method: 'PATCH',
    headers: asAlice,
    body: JSON.stringify({ name: 'Alice Doe' }),
  });

  expect(res.status).toBe(200);
  const user = await fetch(`${DEPLOY}/api/users/alice`, { headers: asAlice }).then((r) => r.json());
  expect(user.name).toBe('Alice Doe');
});

test("updating someone else's name is forbidden", async () => {
  const res = await fetch(`${DEPLOY}/api/users/bob`, {
    method: 'PATCH',
    headers: asAlice,
    body: JSON.stringify({ name: 'Hacked' }),
  });

  expect(res.status).toBe(403);
});
The model proposed the case; Jest measures the outcome. qa.scenarios_passed < qa.scenarios_total is a fact, and the rules gate on it — a confident, wrong model
can't turn a red suite green.
Does it also look right?
Working isn't the same as matching the design. Design checks compare
the rendered preview with your design file — Figma first — and fold the result into
design.* facts the same way.